Haru 4B
For decades, science fiction has imagined AI that can converse with us as naturally as another person — laughing at our jokes, understanding our emotions, and knowing when to speak or stay silent. We believe this vision of human-like AI is what has captivated us for so long.
Natural conversation is more than an exchange of words. It includes spontaneous laughter, backchanneling, interruptions, and even shared silence. These small moments are what make conversations feel genuinely human. Yet the full-duplex technology needed to realize such interactions has not been sufficiently explored.
Today, we are introducing Haru 4B, our end-to-end full-duplex S2S model that can listen and speak simultaneously. We are releasing Haru 4B as an open-weight pre-trained base model, along with the inference code, to encourage research and collaboration. At the same time, we are developing larger-scale models toward our goal of making natural conversations with AI part of everyday life.
1. What Is Haru 4B? — A Real-Time Full-Duplex S2S Model
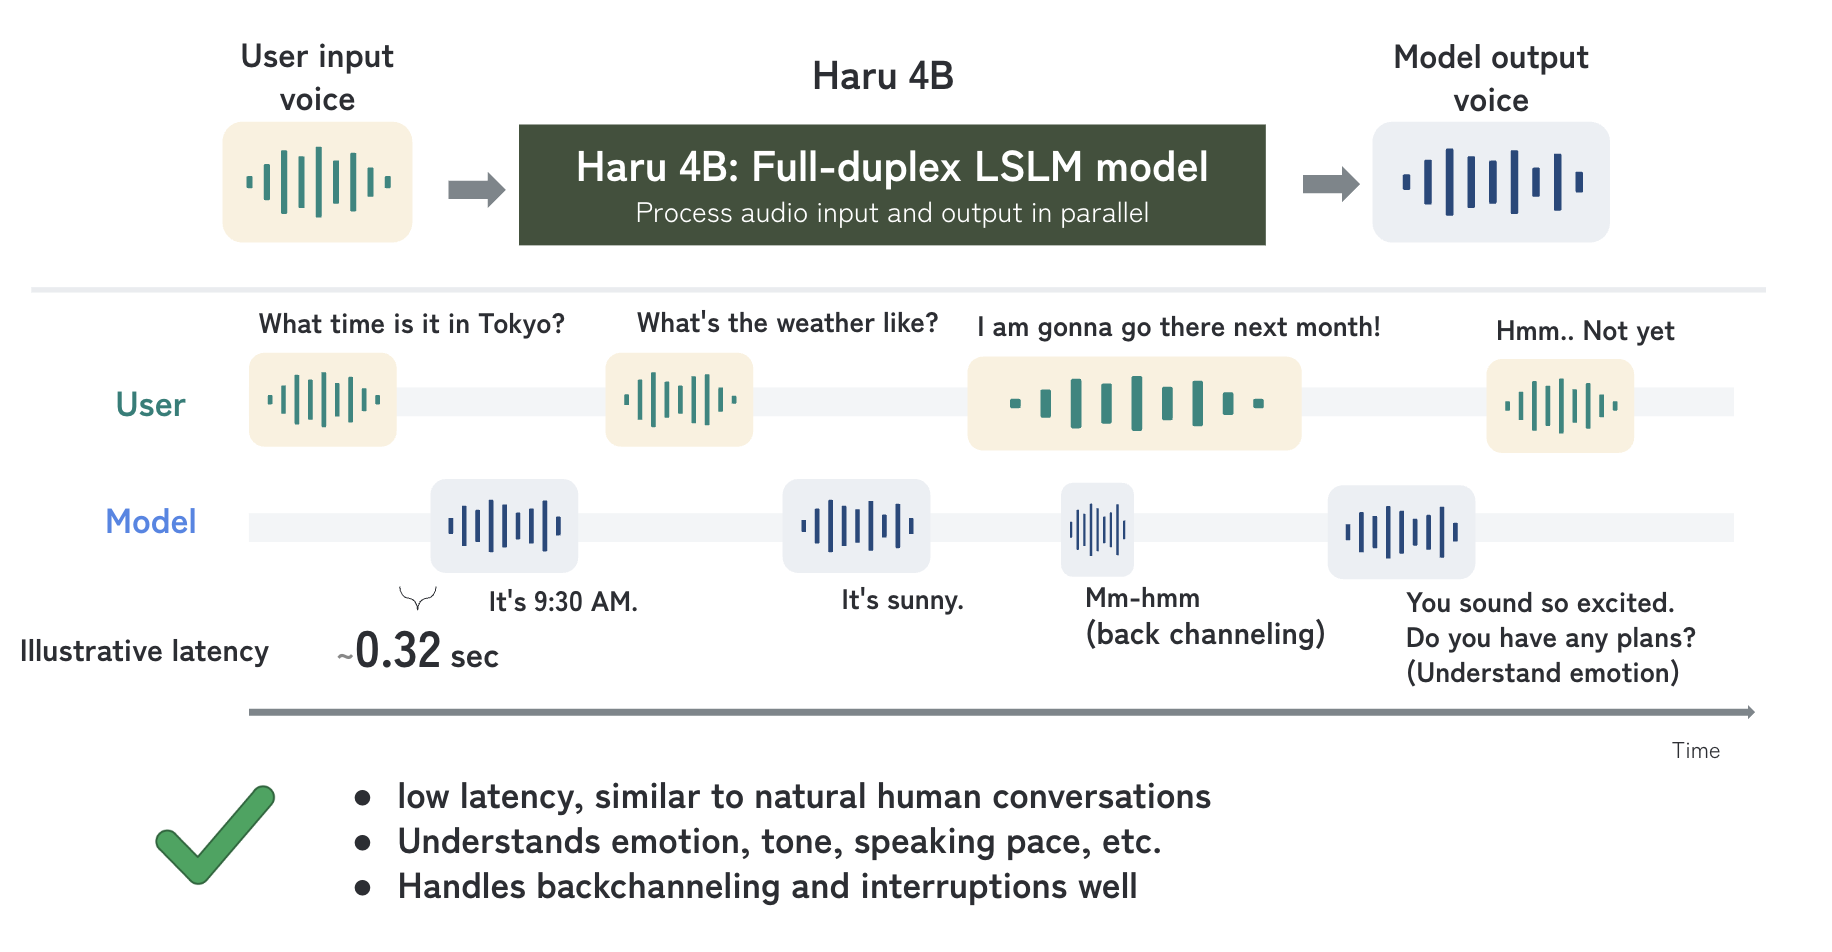
Haru 4B is an end-to-end full-duplex speech dialogue model capable of listening and speaking simultaneously.
Traditional cascaded systems process ASR, LLM, and TTS sequentially. This architecture introduces additional latency and can lose important paralinguistic cues — such as intonation, emotion, and speaking style — when speech is converted into text. Haru 4B instead processes audio directly and learns not only what to say, but also when and how to respond, including backchanneling, interruptions, and overlapping speech.
Figure 1 | Mechanism and Challenges of the Cascaded Model
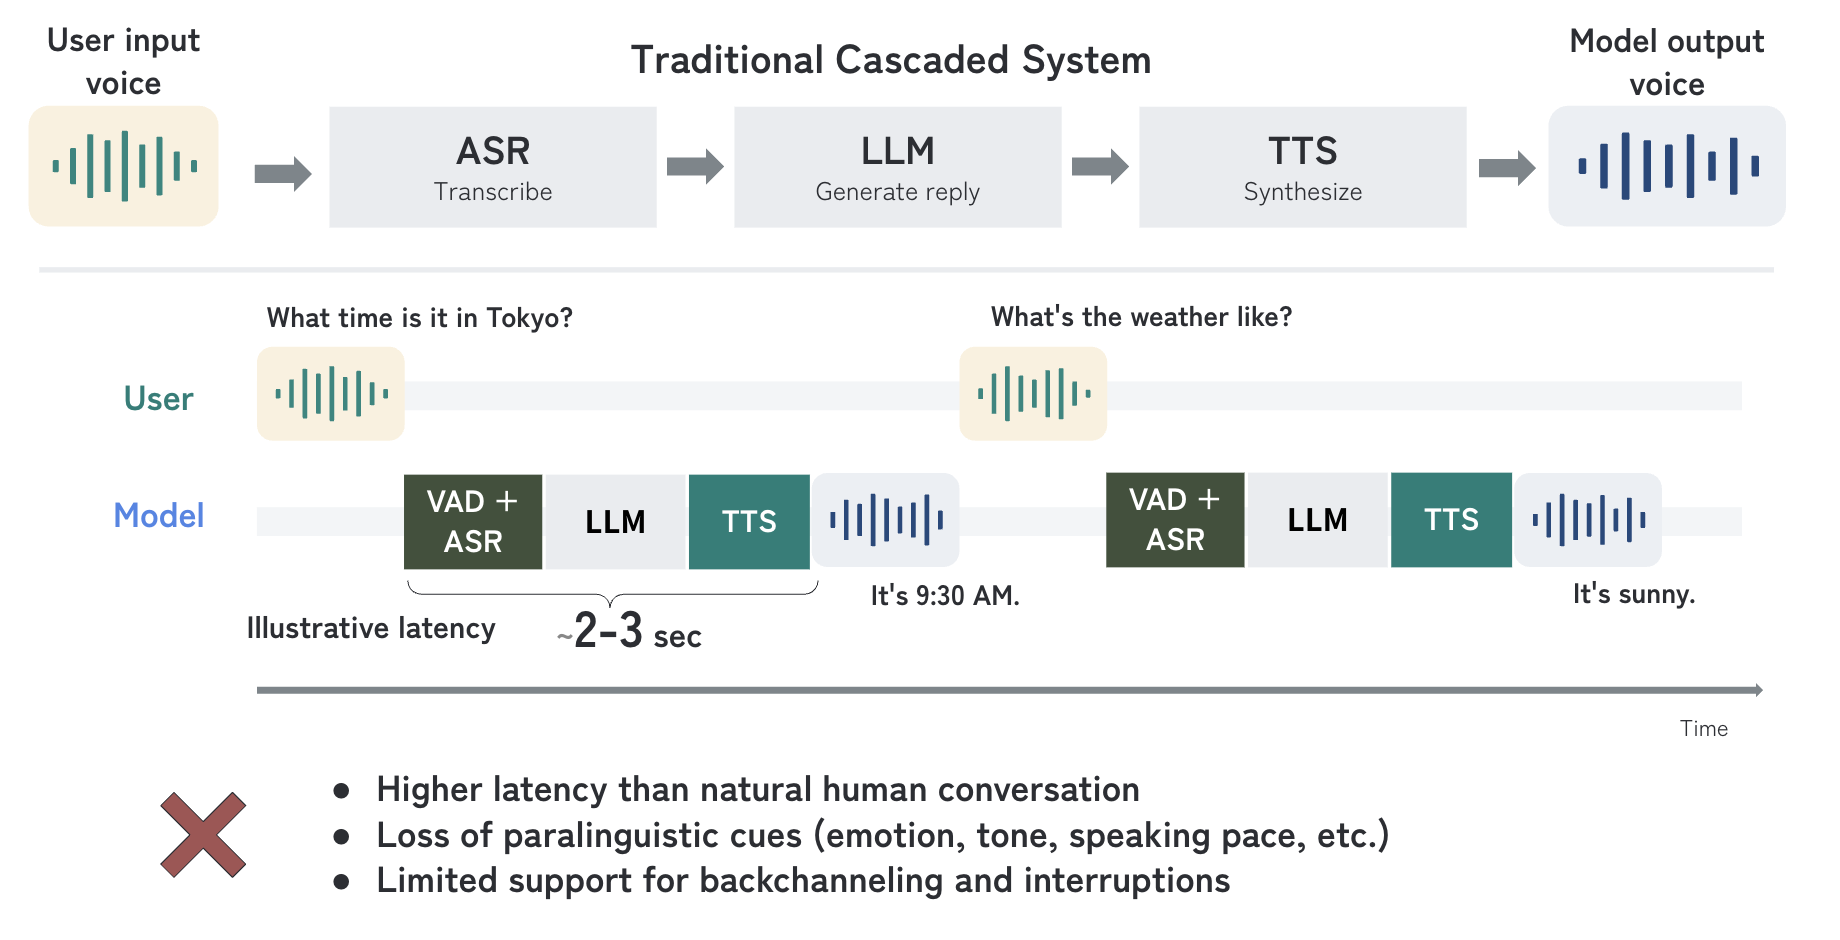
Figure 2 | Haru 4B | Mechanism and Strengths of Full-Duplex LSLM model
2. Listen to Haru — Four Conversation Demos
The best way to understand Haru is to hear it in action. Listen for natural speech, rapid turn-taking, backchanneling, interruptions, and expressive responses.
Demo 01 — Casual Conversation About the Economy (JP)
A casual conversation with a college classmate, featuring natural turn-taking and responsive dialogue.
In this conversation about the economy, Haru responds with timely backchannels and adjusts its emotional tone and speaking pace to the context.
Demo 02 — Casual Conversation About Movies (EN)
Natural conversation about movies, featuring laughter, expressive responses, and smooth handling of overlapping speech and backchannels.
Haru chats about favorite romantic movies, continuing naturally when the user’s backchannels overlap with its speech and building on the conversation.
Demo 03 — Casual Conversation About Parenting (JP)
An expressive conversation about parenting, featuring laughter, empathy, and frequent overlapping speech.
Haru responds naturally to a discussion about parenting, showing empathy, emphasizing key points, and laughing at the user’s jokes.
Demo 04 — A Shift in Conversational Tone (EN)
Haru naturally shifts from casual conversation to a more serious, professional tone as the discussion turns to financial decisions.
3. Architecture
Architecture for Real-Time Multi-Stream Processing
Haru aligns three streams — user speech, model speech, and text — at each time step, allowing a single language model to process incoming speech while generating spoken and textual responses. The streams are synchronized at 7.5 Hz (approximately every 133 ms).
This multi-stream architecture enables Haru to handle backchanneling, interruptions, and overlapping speech as part of a continuous conversation. The low frame rate of 7.5 Hz helps reduce sequence length and computational cost, enabling efficient real-time processing.
Haru 4B multi-stream architecture
Continuous Speech Tokenization
Haru 4B uses the continuous speech tokenizer from VibeVoice (ICLR 2026). It encodes speech into continuous representations at a frame rate of 7.5 Hz, significantly reducing sequence length while preserving acoustic detail. This also helps reduce the computational demands of training and inference.
For more details, read our technical blog.
4. Open Weights, Open Research
We believe that an open research community is essential for realizing human-like AI. For Haru 4B, we are releasing the model weights on Hugging Face and making the inference code available on GitHub. Please note that Haru 4B is a pretrained base model, rather than an instruction-tuned assistant.
We look forward to advancing this field together with researchers and developers around the world.
5. Join Us / Get in Touch
We believe there is still a significant gap between today’s full-duplex models — including Haru 4B — and the human-like AI we envision.
At higurashi, we aim to scale full-duplex S2S models to bring more natural, human-like conversational AI into everyday life. We are looking for researchers and engineers to join us in this effort, particularly those interested in speech models, large-scale training, data processing, inference acceleration, and evaluation.
Let’s Talk
If you are interested in research collaboration, using our models, or API and product integrations, please reach out to us at contact@higurashi.ai.